AI Accuracy: When AI Sounds Sure but Isn’t
Explore why confident AI outputs can still be inaccurate and how better data, validation, monitoring, and human oversight improve reliability.
AI Accuracy Matters Most When
Confident Outputs Influence Real Decisions
AI accuracy is easy to overestimate because modern systems rarely look uncertain. A polished answer, confident prediction, or neatly summarized dashboard can feel authoritative even when the underlying result is incomplete, poorly supported, or simply wrong.
For businesses, the risk is not that AI occasionally makes mistakes. Every analytical system has limitations. The bigger problem is allowing inaccurate outputs to move into marketing, reporting, sales, operations, or customer communication without anyone checking whether they make sense.
This guide explains:
- Why confident AI output should not be confused with reliable output
- Why accuracy can change after a system moves into real-world use
- How businesses can validate AI-assisted work without removing the efficiency benefits
- Which monitoring practices make AI more useful over time
What AI Accuracy
Actually Means in Business
At its simplest, this metric describes how closely an AI system's outputs match an accepted correct result.
Accuracy in a classification model can often be measured against known labels. A forecasting model can later be compared with actual outcomes. A generative AI system used for research, reporting, or customer communication is harder to score because an answer may be partly correct, outdated, incomplete, or unsupported rather than clearly right or wrong.
This is why one headline accuracy percentage rarely tells a business everything it needs to know.
The relevant question is whether the system performs reliably for the specific task it has been given.
A lead-scoring model, for example, should be evaluated on whether its recommendations help identify genuinely valuable prospects. A reporting assistant should be checked against the source data it summarizes. A customer-support assistant should be evaluated on whether its answers are both correct and appropriate for the request.
The same principle applies to automation. Mass Data's guide to auditing a marketing automation stack shows why automation should be evaluated against real business processes rather than assumed to work correctly simply because a workflow runs without errors.
Why Confident AI
Outputs Can Be Misleading
People naturally use communication cues to estimate confidence.
When a colleague says, "I'm not sure, but I think..." we know to verify the answer. AI systems often provide no equivalent warning. The language can remain equally fluent whether the underlying answer is strongly supported or uncertain.
That creates a dangerous shortcut: fluency starts to look like evidence.
A fabricated reference can be written in the same tone as a verified source. A mistaken interpretation of a sales report can sound just as polished as a correct one. An automated summary can confidently explain why performance changed even when the data does not support that explanation.
The problem becomes more serious when the output is embedded inside a workflow.
If someone manually asks an AI tool one question, there is an obvious opportunity to review the answer. If an automated system generates hundreds of classifications, reports, replies, or recommendations, weak outputs can move further before anyone notices.
That is one reason Mass Data's article on building an AI reporting workflow from GA4 data emphasizes the need to understand the data structure and limitations behind automated reporting rather than treating generated summaries as inherently reliable.
How AI Accuracy
Changes After Deployment
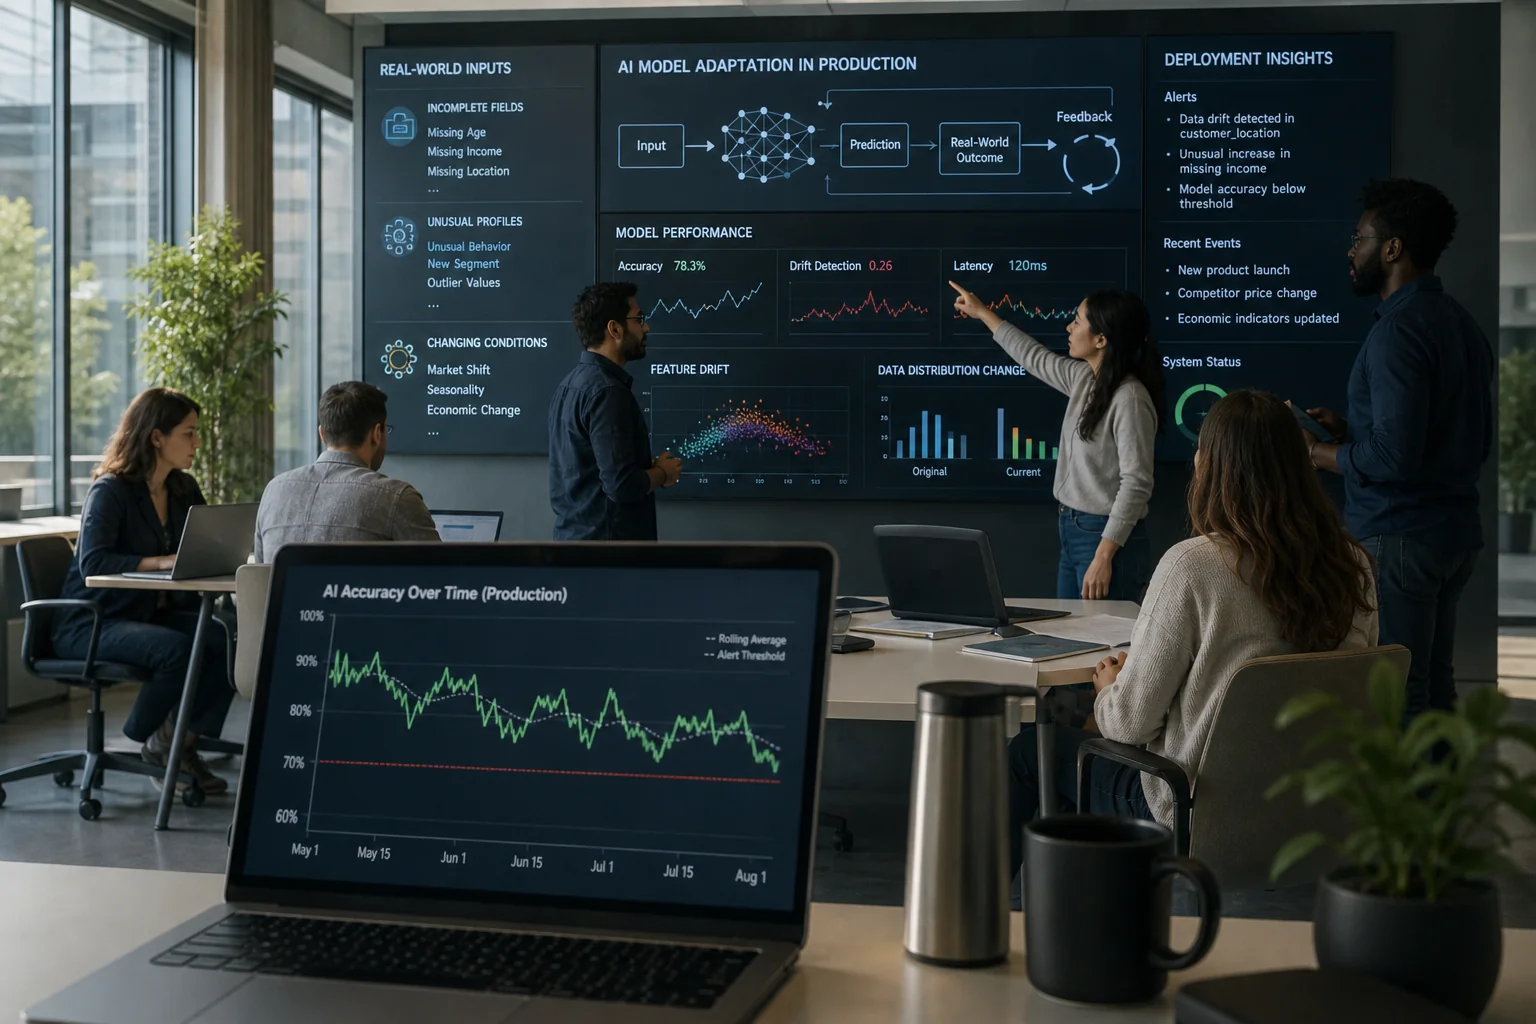
Controlled evaluation and production use are not the same environment.
A model may be tested on carefully prepared data, then encounter incomplete fields, unusual customers, new products, changing language, different market conditions, or edge cases after deployment.
Controlled evaluation and production use are not the same environment, and accuracy measured in testing does not automatically carry over once a system is deployed. Realistic test conditions and ongoing monitoring are generally needed to understand how a system behaves in practice.
This is commercially important because businesses often evaluate AI before implementation and then reduce scrutiny after launch.
That is backwards.
Production is where the system encounters the conditions that matter most.
If customer behavior changes, the signals behind a predictive model may become less useful. If an organization changes how CRM fields are populated, an automated lead-scoring system may begin making decisions from inconsistent data. If a reporting workflow receives a modified export format, summaries may continue appearing normal even though the input has changed.
Accuracy should therefore be treated as something that needs to be maintained, not something permanently established during setup.
Different AI Tasks Need
Different Definitions of Accuracy
There is no single test that works for every AI application.
Imagine four systems: a lead-qualification model, a revenue-reporting assistant, an AI chatbot, and a content workflow.
The lead system can be evaluated against downstream opportunity quality or closed revenue. The reporting assistant can be checked against database totals and approved calculation logic. Customer support can be reviewed for factual correctness, policy compliance, and successful resolution. Content may need source verification, editorial review, and brand-quality checks.
This means businesses should define accuracy before they attempt to measure it.
A useful framework is to ask what an error looks like, how expensive that error could be, and how quickly someone would notice it.
For example, a minor wording issue in an internal draft has limited impact. Incorrect pricing sent automatically to hundreds of customers is very different.
Mass Data's article on AI customer support for marketing agencies illustrates the same boundary: some interactions can be automated efficiently, while others still require human involvement because context and judgment matter.
Build Verification Around the
Cost of Being Wrong
Not every AI output deserves the same level of review.
Businesses will lose much of the value of automation if employees manually verify every low-risk action. But allowing high-impact decisions to run without oversight creates unnecessary exposure.
The better approach is risk-based verification.
For high-impact workflows, the control layer can include:
- Comparing AI outputs with authoritative source data
- Requiring human approval before consequential actions
- Sampling automated outputs regularly for quality checks
- Tracking error patterns instead of looking only at an average score
- Creating escalation rules when confidence or data quality falls below an agreed threshold
The key is to make verification part of the workflow rather than something teams remember only after a mistake occurs.
For lead management, this could mean comparing AI-selected prospects with eventual sales outcomes. Mass Data's guide to how AI lead qualification works beyond the vendor pitch explains why scoring models need to reflect the company's real definition of a valuable lead instead of generic assumptions.
Data Quality Can Limit
Accuracy Before AI Even Starts
Organizations sometimes blame the model for problems created upstream.
AI cannot reliably compensate for duplicate CRM records, inconsistent naming conventions, missing conversion events, incorrect product information, or disconnected data sources.
If the input is unreliable, the output may simply make unreliable information easier to consume.
This matters particularly in marketing and analytics because businesses frequently combine data from advertising platforms, CRMs, ecommerce systems, analytics tools, spreadsheets, and finance systems.
One system might define a lead differently from another. Revenue can be recorded using different currencies or attribution rules. A campaign name can change halfway through the month. The AI layer then receives information that looks structured but is not necessarily comparable.
Before asking how to make an AI model more accurate, check whether the source data is fit for the task.
This is where a stronger data infrastructure becomes commercially useful. Mass Data's data analytics and business intelligence services focus on integrating disconnected marketing, CRM, ecommerce, financial, and analytics data into reporting structures that can support more reliable decision-making.
Monitoring and Feedback Are What
Make AI Useful Over Time
The most practical approach is not expecting perfection from AI systems.
It is creating a system where important mistakes are detectable, measurable, and correctable.
That requires feedback.
If sales teams routinely override AI lead recommendations, that information should be captured. If a reporting assistant misinterprets a particular metric, the workflow should be adjusted. If customers repeatedly escalate one type of chatbot answer, that category should be reviewed.
Without feedback, a business can continue running the same automation while employees quietly work around its weaknesses.
Monitoring should therefore include both quantitative and qualitative signals.
A model may still achieve a good overall score while performing badly for a commercially important segment. A chatbot might answer most questions correctly but fail consistently on refunds. A reporting assistant may summarize traffic perfectly while misinterpreting revenue because one field changed.
The objective is not merely to ask, "Is the AI accurate?"
A better question is, "Where does it fail, how often does that happen, and what is the business impact?"
Companies introducing AI into multiple workflows may also benefit from treating implementation as an operating system rather than a collection of tools. Mass Data's AI marketing automation and integration services focus on connecting automation with business data and measurable outcomes rather than adding AI simply because the technology is available.
A Hypothetical Example: The Client
Report That Looked Completely Correct
Consider a hypothetical marketing agency that automates monthly client reporting.
Campaign data flows into a central reporting system. An AI assistant analyzes performance and drafts a written explanation of what changed during the month.
For several months, the system works well.
Then one advertising platform changes how a field is imported. Revenue still appears in the dataset, but a portion is now assigned differently.
The AI assistant does not recognize that anything has changed.
It produces a polished explanation stating that a campaign generated a strong increase in revenue because a new targeting strategy performed better.
The explanation sounds logical.
But the campaign did not actually improve. The underlying data changed.
A strategist reviewing only the generated paragraph might approve it. Someone checking the AI summary against the underlying revenue source would notice the discrepancy.
The agency responds by adding validation rules. Revenue totals are compared with an independent source before the AI summary is generated. Material discrepancies trigger manual review.
The system remains automated, but the accuracy control is placed where an error can do the most damage.
This is the commercial lesson behind AI accuracy: the best systems are not those that never fail. They are systems designed so that meaningful failures are difficult to miss.
Common Mistakes When
Businesses Evaluate AI Accuracy
The first mistake is relying on a single accuracy number without understanding how it was measured.
A benchmark result means little if the test does not resemble the environment where the system will actually operate.
Another mistake is reviewing AI only during implementation. Models, data, customers, markets, and workflows change. Validation needs to continue after deployment.
Businesses also make the mistake of treating every error equally. A small classification mistake and an incorrect financial recommendation may both count as one error statistically, while their business consequences are completely different.
Another risk is assuming human review automatically solves the problem. Reviewers need access to the evidence required to verify an answer. Asking someone to approve an AI-generated analysis without showing the source data creates the appearance of oversight rather than meaningful oversight.
Finally, teams sometimes respond to inaccuracies by adding more AI tools. Additional automation is unlikely to solve a problem caused by weak data, unclear objectives, or missing validation.
The better response is to identify exactly where reliability breaks down and fix that part of the system.
Conclusion: Better AI Accuracy
Comes From Better Systems
AI accuracy should not be treated as a score that proves a system is safe to trust indefinitely.
Reliability depends on the quality of the data, the task being performed, the environment in which the system operates, and the controls surrounding its output. As those conditions change, performance can change with them.
Businesses do not need perfect AI to benefit from it. They need systems that are sufficiently reliable for their intended purpose and controls that catch mistakes before those mistakes become expensive.
That means validating important outputs, monitoring production performance, maintaining clean data, documenting known limitations, and keeping human judgment where the cost of being wrong is high.
The competitive advantage is not trusting AI more. It is knowing when to trust it, when to verify it, and how to detect when its behavior changes.
Questions
Answered
Common questions related to this topic.
1. What constitutes AI accuracy?
AI accuracy is the measure of how often an AI system's predictions align with actual outcomes, typically expressed as a percentage of correct predictions.
2. Why is AI sometimes inaccurate?
AI can be inaccurate due to poor data quality, overfitting, ambiguity in the data, and the complexity of real-world problems that are difficult for AI to model accurately.
3. How can businesses improve AI accuracy?
Businesses can enhance AI accuracy by conducting regular audits, using diverse datasets, ensuring human oversight, and implementing feedback loops to refine AI models.
4. What are the risks of relying too heavily on AI?
Overreliance on AI can lead to poor decision-making, especially if the AI's predictions are not verified. This can result in significant financial and reputational repercussions.
5. How do ethical considerations impact AI accuracy?
Ethical considerations around AI accuracy involve accountability, bias, and fairness. Organizations must navigate these issues to ensure responsible AI use.
6. What is the future of AI accuracy?
The future of AI accuracy will likely involve improved algorithms, better training data, and a more significant emphasis on ethical practices, leading to more reliable outcomes.
Ready To GrowThis Into Results?
Explore why confident AI outputs can still be inaccurate and how better data, validation, monitoring, and human oversight improve reliability.
Prefer to reach out directly? We'll get back to you as soon as possible.
Contact MASS DATA Today

